Impact analysis
Deterministic code graphs — architecture, change and impact maps — with file:line on every edge, and recall verified by mutation testing instead of asserted.
allo@alloevil:~$ whoami
Evidence-first tooling for AI coding agents.
Don't trust the model's self-report — check it. Every project here exists because an LLM asserted something that turned out to be false: a diagram that was an opinion, a judge score that could be bluffed, a benchmark number with no source.
What I do
Every tool in this profile came out of the same failure mode — a plausible statement nobody could reproduce. The fix is mechanical: print the evidence, or don't publish the number.
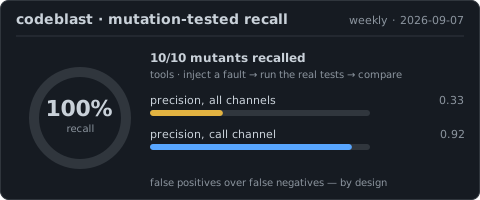
Deterministic code graphs — architecture, change and impact maps — with file:line on every edge, and recall verified by mutation testing instead of asserted.
Program gates before rubrics, paired statistics for the verdict, and a written statement of what the verdict cannot rule out. Zero dependencies.
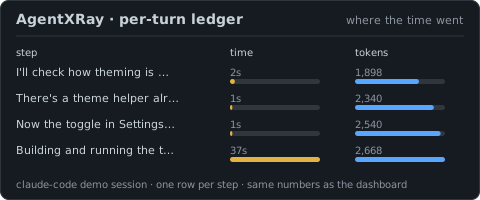
Read what the agent actually did — turn by turn, token by token, with the cost column when the session reports one.
Featured work
The cards below are read from projects/projects.json at
load time — the same file the project index and claims.json check against, so a card cannot
describe a project the index does not list.
Evidence, not widgets
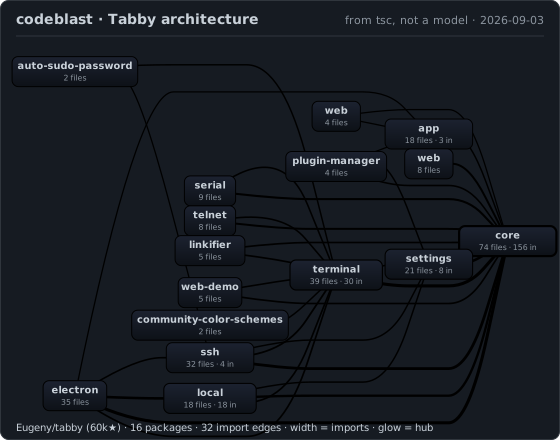
Rendered on a schedule from the tools' own results, and served from the image branch this repository publishes: codeblast's dependency graph, its mutation-tested recall, an AgentXRay per-turn ledger, and the contribution grid.

Writing
Post titles and dates come from the blog's front matter, listed in
blog/posts.json.
This site is one repository: the pages, the data files they render, and the
claims.json that recomputes what the pages say. Push to main and Cloudflare
Workers Builds rebuilds and deploys it.